September 2026

Cloud Run finally adopted an insomniac

My AI agent hung up on me after exactly five minutes. It did not wait for four minutes, nor did it stretch to six. The line went dead at five minutes flat, displaying the sterile punctuality of a scheduled dental cleaning and the interpersonal warmth of a parking meter. I reconnected. Five minutes later, another hang-up. I reconnected yet again, driven by that specific primate delusion that makes humans violently mash an elevator button that is already glowing. Five minutes.

This is the clinical record of how that aggressively rude disconnection finally explained to me why Google issued a fourth child to the Cloud Run family, and why this particular infant absolutely refuses to go to bed.

A family that already reached maximum occupancy

Cloud Run is the designated quarantine zone where most of my experiments go to live, especially the ones involving artificial intelligence workloads. Therefore, when Google announced Cloud Run instances in preview, my initial reaction was not one of boundless joy. It was the haunted expression of an exhausted parent being told that yet another sibling is on the way. Cloud Run already possessed three execution models, and they seemed to cover every conceivable household chore:

  • Services, the aggressively sociable one. This sibling greets every single visitor, answers every request, and drops into a deep coma the exact millisecond the last guest leaves the living room. The marketing brochure politely refers to this narcolepsy as “scaling to zero.”
  • Jobs, the brooding teenager who shows up, runs a five-hour load of heavy laundry, and departs without saying goodbye or making eye contact.
  • Worker Pools, the subterranean dweller. It lives in the basement, quietly pulls tasks from a queue, and possesses no public URL. Nobody has its phone number. Nobody asks how its day went.

Why did we need a fourth? What bizarre task could this new arrival possibly execute that the other three could not handle between them?

(A brief warning about vocabulary before we proceed. Cloud Run already utilized the word “instance” for the container copies a Service spins up when it scales. Now there is a separate product officially named Cloud Run instances. This linguistic choice means the sentence “my instance ran out of instances” is now grammatically valid. Sooner or later someone will say this in a corporate meeting with a completely straight face. For our purposes, “Instance” with a capital I refers to the new product. When in doubt during your daily life, ask the speaker which instance they mean. Then ask them again just to be safe.)

The experiment that worked and explained absolutely nothing

My plan was to find the justification for this new product empirically. I would build an AI agent that runs long-lived sessions and keeps temporary data locally, deploy it as a regular Cloud Run Service, and watch it fail spectacularly. The failure would reveal the true purpose of Instances.

I mounted a Cloud Storage bucket as a volume and gave the agent a tool to read and write its session state there. I added an ephemeral disk for the scratch data it produced mid-task. Then I sat back and waited for the disaster.

Disaster did not come. The agent handled long sessions without complaint. It scaled to zero when ignored, costing me nothing, and when I called it later it picked up the exact same session as if it had just stepped out for a coffee. Scientifically speaking, this was the worst possible outcome. A total success without any comprehension of the underlying mechanics is just a failure with an excellent public relations team.

Of course, the setup was deeply flawed. Cloud Storage mounted through FUSE (Filesystem in Userspace) is less like a modern hard drive and more like trying to maintain a deep, philosophical conversation by sending telegrams via carrier pigeons with bad attitudes. The latency is palpable, and real POSIX file locking is completely off the menu. The ephemeral disk, meanwhile, was wiped completely clean every time the service scaled to zero. It was like hiring an overzealous sanitation team that incinerates your filing cabinets the moment you step out for a bathroom break.

But here is the catch. None of those problems justified the new Instances product, because an Instance would suffer from the exact same storage limitations. My confusion had metastasized into a peer-reviewed finding.

The waiter who violently confiscates your plate

The breakthrough arrived when I stopped thinking of agents as people who mail letters and started thinking of them as people who make phone calls.

Request and response is letter writing. A question goes out, an answer comes back, and the mailbox goes quiet. That is the natural habitat of a Cloud Run Service. But many long-running agents do not write letters. They open a WebSocket and keep it perpetually open, pushing a steady trickle of updates back to the user. That is a phone call meant to stay active for hours.

When I rebuilt my agent using this methodology, I met the five-minute hang-up from the first paragraph. The culprit was the request timeout. On a Cloud Run Service, a WebSocket connection is treated as a standard request, and every request has a deadline. You can stretch this maximum timeout to 60 minutes. To a long-running AI agent, sixty minutes is equivalent to a waiter staring unblinkingly into your eyes while ripping the plate from your hands and charging you for the privilege of not swallowing your food.

This is precisely the gap Cloud Run instances fill. Unlike Cloud Run services that scale based on incoming traffic, an Instance is a dedicated compute container managed manually through lifecycle transitions (create, stop, start, update, delete). It gets an HTTPS address that survives updates and restarts. It holds connections open. It does not suffer from narcolepsy when traffic stops. It is the insomniac cousin who always picks up the phone at three in the morning.

Creating one requires a single beta command. Just remember to keep IAM invoker authentication enabled. Bypassing IAM is fine for a quick demo, but for an AI agent with access to your calendar and inbox, you probably do not want it casually chatting with the entire internet.

What the insomniac actually does for a living

Long-running AI agents got me through the door, but they are not the only tenants suited for this environment.

Personal agents and workflow engines. If I run an automation tool like n8n or a personal agent for myself, I do not need it to scale to a thousand users. I need it awake, holding its state, and reachable at a stable URL that refuses to hang up after an hour. This is the flagship use case.

A quick bastion host. Giving developers access to a private database usually requires provisioning a Virtual Machine and babysitting SSH keys, which is the IT equivalent of building a dedicated two-story garage just to store a single garden rake. Now, developers can use Instances as bastion hosts to reach internal resources. Just check the current documentation, because SSH access for this preview product changes rapidly.

Sandboxes and code playgrounds. Sometimes you just need an addressable box to execute code you do not entirely trust, a playground you fully intend to delete next week. Pair an Instance with Cloud Run sandboxes, and you get that environment without standing up a massive Kubernetes cluster.

The argument for Instances is not raw capability. A dedicated Virtual Machine can do all of this. The argument is convenience and price. Running an Instance with 1 vCPU and 1 GiB of memory continuously for a month costs around $5.70. Unlike a vending machine sandwich of the exact same price, this compute container will not give you severe heartburn, though its absolute lack of local persistent storage might cause a mild nervous breakdown. The insomniac does its own laundry, saving you from patching operating systems or provisioning HTTPS endpoints.

The fine print, read aloud in a clinical setting

Every adoption comes with paperwork. Here is the part of the file the agency hoped you would not read.

It is a goldfish. An Instance is a singleton with zero autoscaling. It is cheap and low maintenance, but if you overfeed it, it floats belly-up. When your app gets a sudden spike in traffic, Cloud Run will not spin up a helpful sibling. Requests will queue politely until they quietly die of old age. Internet users love to tap on the server glass until the poor fish suffers a fatal HTTP-induced collapse. Keep IAM authentication turned on so strangers cannot overfeed a goldfish they cannot reach.

It has nowhere safe to keep its things. An Instance feels like a VM, but it has no local persistent disk. Anything written to the temporary folder lives in the container’s memory, so your scratch files compete directly with your application for RAM. It is like storing your weekly groceries in your jacket pockets.

It suffers from weekly amnesia. Instances can stay active for up to seven days before a mandatory restart policy kicks in. When that happens, everything in memory and on the ephemeral disk is instantly vaporized. Think of a corporate office worker who suffers a blunt-force head trauma every Sunday at midnight. They show up on Monday morning smiling, with their tie on backward, having absolutely no recollection of their own name, waiting for an external database to explain who they are. Anything that must survive this reboot belongs in a bucket.

It is still in preview. Running production workloads on a preview product is not strictly forbidden. It is just the infrastructure version of moving your living room furniture into a house while the construction crew is actively sawing the legs off the staircase.

A Field Guide to the Cloud Run Household

By the end of my investigation, the entire Cloud Run family finally made clinical sense. Since tables tend to break when viewed on mobile phones, think of this as a highly practical survival guide for your next architectural decision:

  • The Service: Reach for this when you need a web app or API that scales massively with traffic and takes a nap when idle.
  • The Job: Reach for this when you have a batch task that runs for hours and then permanently clocks out.
  • The Worker Pool: Reach for this when you need background workers pulling from a queue, hiding safely from the public internet.
  • The Instance: Reach for this when you need one always-on container with a stable URL that holds connections for days without hanging up.

The first three members of the family were built around the very reasonable idea that you should not pay for a machine that is not actively working. The new sibling is built around a different, equally reasonable idea: some things are only useful if they are completely awake when you call them.

So yes, Cloud Run adopted an insomniac. It costs about as much as a sad sandwich, it answers the phone at any hour, it violently forgets its own identity once a week, and it will panic if more than a handful of people speak to it simultaneously. I have worked with human beings exactly like that. Some of them were excellent colleagues.

Just remember, when you tell your team you are “moving the agent to an instance,” clarify exactly which instance you mean. Then clarify it again, just to be safe.
Tricking Terraform to test your infrastructure locally in seconds

There is a very specific type of agony associated with waiting for cloud resources to spin up. You write your infrastructure code, you push it to the server, you stare at a loading spinner, and you visibly age. By the time your database is finally ready to accept connections, you have completely forgotten why you needed a database in the first place.

Real infrastructure lives in Terraform. If local development is going to be genuinely useful to us, it needs to speak that exact same language. But we do not want to wait, and we certainly do not want to pay Jeff Bezos every time we run a unit test.

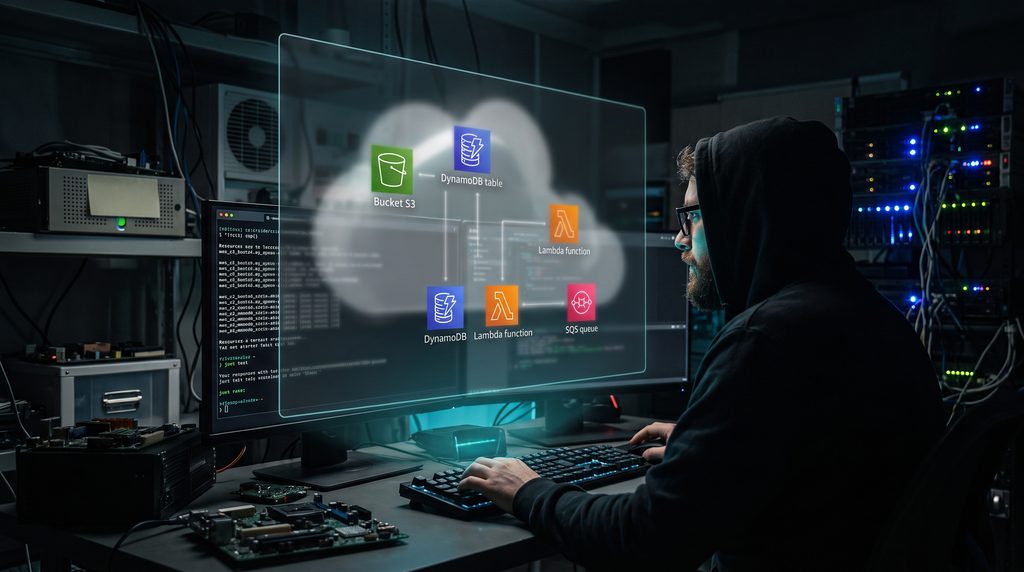
The solution is an elaborate digital heist. We are going to put a pair of virtual reality goggles on Terraform so it believes it is negotiating with the almighty AWS billing engine. In reality, it will be chatting with a humble local container running MiniStack on your laptop. Terraform will behave exactly as it would against the real cloud, totally oblivious to our little conspiracy.

This guide covers two distinct crimes against cloud computing. First, we will point your actual Terraform configuration at MiniStack instead of a real AWS account. Second, we will use that same setup to run full integration tests on your machine in seconds.

Constructing the cardboard storefront

MiniStack acts as a drop-in endpoint override for Terraform. You do not need a special plugin, and you can skip the usual agonizing authentication dance involving temporary tokens and multi-factor prompts. You simply point the AWS provider at your localhost port 4566, hand it some aggressively fake credentials, and let it do its job.

The most explicit way to pull off this trick is by adding an endpoints block to your provider configuration. This acts like a fake storefront, redirecting Terraform’s serious API calls into our local container.

provider "aws" {
  region                      = "eu-central-1"
  access_key                  = "fake_access_key"
  secret_key                  = "fake_secret_key"
  s3_use_path_style           = true
  skip_credentials_validation = true
  skip_metadata_api_check     = true
  skip_requesting_account_id  = true
endpoints {
    s3       = "http://localhost:4566"
    dynamodb = "http://localhost:4566"
    sqs      = "http://localhost:4566"
    lambda   = "http://localhost:4566"
    iam      = "http://localhost:4566"
  }
}

I prefer starting with this explicit block because it is completely transparent. You can see exactly which services are being hijacked and sent to your local machine. If you only list the specific services you are actually using, this block conveniently doubles as a tidy inventory of your stack.

If you prefer to avoid maintaining this list by hand, a handy Python wrapper called tflocal will generate it for you automatically. You just install it via pip and run tflocal apply instead of your usual Terraform commands. It behaves identically, making it an easy substitute in any workflow.

Hiding the heavy machinery in the basement

It is incredibly tempting to spin up a Lambda function, a message queue, and a database using a dozen individual command-line instructions. That is fine for a quick afternoon experiment, but it is a terrible way to manage real software.

A production environment requires these resources to be properly defined in Terraform. I will spare you the visual trauma of scrolling through a massive hundred-line configuration file. I have placed the entire, glorious, fully functional Terraform manifest in a GitHub repository for those who enjoy copying and pasting wholesale infrastructure.

For the sake of our sanity here, let us just look at a tiny slice of the pie. We want to provision a DynamoDB table for tracking lost laundry items and a Lambda function to process them. Here is how standard and boring the configuration looks, completely devoid of any local-testing hacks.

resource "aws_dynamodb_table" "lost_laundry" {
  name         = "lost_socks_inventory"
  billing_mode = "PAY_PER_REQUEST"
  hash_key     = "sock_id"

  attribute {
    name = "sock_id"
    type = "S"
  }
}
resource "aws_lambda_function" "laundry_worker" {
  function_name = "sock_matcher"
  runtime       = "nodejs20.x"
  handler       = "index.handler"
  role          = aws_iam_role.dummy_lambda_role.arn
  filename      = "${path.module}/../sock_matcher_code.zip"
  
  environment {
    variables = {
      TABLE_NAME = aws_dynamodb_table.lost_laundry.name
    }
  }
}

When you run an apply command against this setup, it creates the resources locally. They are reproducible, they are safely version-controlled, and they are mathematically identical in shape to whatever you will eventually deploy to a real data center.

Poking the mirage with actual code

Here is where this bizarre local loop graduates from a neat party trick to a genuinely powerful tool. You can spin up MiniStack, apply your Terraform configuration, run real integration tests against the provisioned resources, and tear it all down.

Instead of clicking through a web console and waiting for a database to spawn while your coffee slowly turns into iced coffee, everything happens locally. A minimal Jest integration test hitting our fake infrastructure looks exactly like a real one.

const { SQSClient, SendMessageCommand } = require('@aws-sdk/client-sqs');
const { DynamoDBClient, GetItemCommand } = require('@aws-sdk/client-dynamodb');

const localConfig = {
  endpoint: 'http://localhost:4566',
  region: 'eu-central-1',
  credentials: { accessKeyId: 'fake', secretAccessKey: 'fake' },
};

const sqs = new SQSClient(localConfig);
const dynamo = new DynamoDBClient(localConfig);

test('worker processes a lost sock notification into the database', async () => {
  await sqs.send(new SendMessageCommand({
    QueueUrl: 'http://localhost:4566/000000000000/laundry_queue',
    MessageBody: JSON.stringify({ sock_id: 'argyle-001', status: 'missing' }),
  }));

  // Wait a brief moment for the event mapping to trigger our Lambda
  await new Promise((resolve) => setTimeout(resolve, 2000));

  const result = await dynamo.send(new GetItemCommand({
    TableName: 'lost_socks_inventory',
    Key: { sock_id: { S: 'argyle-001' } },
  }));

  expect(result.Item).toBeDefined();
  expect(result.Item.status.S).toEqual('missing');
});

This is the beautiful part. This test is not hitting a polite JavaScript mock or a hardcoded stub. It is sending a real message payload through a real routing queue, triggering an actual local Lambda invocation, and reading the resulting data back out of a local DynamoDB instance. It does all of this in the fraction of a second it takes a normal test suite to run.

The automated sandcastle stomping machine

Running this locally is great for your own mental health, but wiring it into Continuous Integration is where the real magic happens. Every single pull request can now provision a full copy of your infrastructure, run tests against it, and destroy it.

Building this up just to immediately tear it down is the digital equivalent of constructing an architecturally flawless sandcastle and then joyfully stomping on it.

jobs:
  phantom-integration-tests:
    runs-on: ubuntu-latest
    services:
      ministack:
        image: ministackorg/ministack:latest
        ports:
          - 4566:4566
    steps:
      - name: Checkout the laundry code
        uses: actions/checkout@v4

      - name: Install Terraform
        uses: hashicorp/setup-terraform@v3

      - name: Build the fake infrastructure
        run: |
          cd infrastructure
          terraform init
          terraform apply -auto-approve

      - name: Run the integration suite
        run: npm run test:integration

No AWS account is ever touched. No unexpected bills arrive at the end of the month. No developer sits around waiting five minutes for a queue to provision just to find out they made a typo in a variable name.

Incompetent security guards and other minor tragedies

There are a few sharp edges to this workflow that you should know about before you fully commit to the illusion.

First, we need to talk about Terraform state handling. You must decide up front whether your local Terraform state should persist between runs or reset every time. For CI environments, you absolutely want a blank canvas. Both the Terraform state and the MiniStack container state should be annihilated on every run. Do not try to recycle a local terraform.tfstate file across automated runs.

Second, we need to address the elephant in the room regarding permissions. MiniStack is wonderful, but when it comes to Identity and Access Management, it acts like a nightclub bouncer who is asleep on a barstool. MiniStack will happily let Terraform create a role with entirely incorrect permissions. Your Lambda could be given a policy that only allows it to read from an S3 bucket, but MiniStack will still let it write to DynamoDB.

Your integration tests will pass with flying colors because MiniStack simply does not enforce IAM boundaries strictly. A green test suite in this local setup confirms that your application logic works flawlessly. It absolutely does not confirm that your IAM policies are correct. You still need a real cloud environment, or a dedicated policy linter, to prevent a permissions disaster in production.

Finally, beware of provider version drift. MiniStack tracks the AWS API closely, but if you upgrade to the absolute newest Terraform provider the day it is released, there might be a short lag before new resource attributes are supported locally. If an apply command suddenly fails with an unrecognized attribute error, check your provider versions before you start questioning your own sanity.

We have reached a point where the local development loop is actually pleasant. We can define our infrastructure, apply it against a local container, run real integration tests against local services, and tear it all down on every single code change. We get all the confidence of testing against the cloud with none of the waiting, and more importantly, none of the invoices.

The mysterious disappearance of your Bash variables

You stare at the screen. A clunky while loop sits there, tasked with processing exactly one single line of text. It looks like a grown adult wearing inflatable arm floaties in a puddle. It is offensive to your sensibilities as a clean, efficient programmer.

Here is the offending legacy code, minding its own business:

echo "Sector_7G" | while read -r zone; do
    echo "Deploying update to $zone"
done

There is only one line of input coming from that echo command. Wrapping a while loop around a single item is administrative overkill. You decide to fire the useless middle management. Why keep a loop when you can simply pipe the value directly into the read command and print it out on the next line?

You swiftly refactor the code into a sleek, modern masterpiece of brevity:

echo "Sector_7G" | read -r zone
echo "Deploying update to $zone"

The two versions look like they should produce the exact same result. They do not.

The first version successfully prints your deployment message. The second version, your beautifully optimized creation, prints a depressing half-sentence: Deploying update to.

At first, this makes absolutely no sense. The read command clearly received the input. The script did not freeze and wait for you to type something on the keyboard, which means the text from the echo command was successfully swallowed by read. The problem is what Bash decided to do with your variable immediately afterward.

A bureaucratic murder mystery

To understand where your variable went, you have to understand how the pipe operator actually functions. The vertical bar | is not a simple plumbing tube that gently moves water from one place to another. In the world of Bash, a pipeline is a paranoid corporate temp agency.

In Bash, every command in a pipeline is executed in its own isolated environment, known as a subshell.

When you type echo “Sector_7G” | read -r zone, Bash refuses to let your main script handle the incoming data directly. Instead, it hires two temporary workers. One temp worker is hired solely to shout the word “Sector_7G“. The second temp worker, confined to a tiny, soundproof cubicle called a subshell, is hired to execute the read command.

The read command does exactly what you asked. It wakes up in its temporary cubicle, catches the text coming through the pipe, proudly writes it on a sticky note labeled $zone, and slaps it on the desk. The temp worker is happy. They have successfully assigned the variable.

But the exact millisecond the pipeline finishes executing, Bash acts as a ruthless corporate liquidator. It fires the temp worker, incinerates the cubicle, and shreds every single sticky note inside it.

When the script moves to the next line of your code to print the message, it is running in the parent shell. This is the executive boardroom. The parent shell has absolutely no idea what happened down in the temporary cubicles. To the parent shell, the variable $zone is completely empty because the employee holding it no longer exists.

This explains why your original, clunky while loop actually worked. The echo statement was trapped inside the loop, meaning it was executed inside the exact same temporary cubicle as the read command.

Taking hostages in the cubicle

Now that we know the pipe operator is essentially an incinerator for local variables, how do we fix the optimization without reverting to a pointless while loop? You have a few clever options for tricking the bureaucracy.

If you absolutely must keep the pipeline, you can use curly braces to group your commands together. This forces both the data reading and the subsequent actions to execute inside the same doomed environment.

echo "Sector_7G" | { read -r zone; echo "Deploying update to $zone"; }

This is basically a hostage situation. You know the temporary office is going to be burned to the ground in a fraction of a second, so you force the worker to finish the entire presentation and broadcast the results before the corporate security guards arrive. The variable is still trapped in a subshell, but since you are utilizing it from within that same confined space, it works perfectly.

Bypassing the mailroom entirely

If you want a cleaner script, you should avoid the temp agency altogether. Process substitution is the modern, preferred way to handle this problem.

Instead of piping data forward into a read command, you redirect the output of a command block directly into the input stream of your main shell. It looks like a slightly confused bird beak, but it is highly effective.

read -r zone < <(echo "Sector_7G")
echo "Deploying update to $zone"

There is no pipeline here. You have completely bypassed the subshell creation protocol. It is the equivalent of installing a pneumatic tube that shoots the document directly onto your executive desk. The read command executes in your primary, current shell, which means your shiny new variable is saved exactly where you need it, safe from incineration.

The lazy desk slap method

Sometimes you do not need a pneumatic tube. If you are just passing a simple string of text or the evaluated result of a basic command, you can use a here-string. This is denoted by three consecutive less-than signs.

read -r zone <<< "Sector_7G"

Like process substitution, this completely avoids pipelines and subshells. It is the administrative equivalent of walking into the office and slapping the raw data directly onto the read command’s desk without filling out any requisition forms. It is fast, slightly dirty, and entirely immune to the subshell vanishing act.

The dark magic corporate loophole

Perhaps you are a Bash purist. You insist on using standard vertical pipes, you refuse to use curly braces, and you demand that your variables survive the process. If you are running Bash version 4.2 or newer, there is a bureaucratic loophole you can exploit.

You can flip a magic switch at the absolute top of your script.

shopt -s lastpipe
echo "Sector_7G" | read -r zone
echo "Deploying update to $zone"

The lastpipe option is a buried corporate policy that tells Bash to change how it handles the assembly line. It mandates that the very last command in any pipeline gets a full-time contract. Instead of spawning a doomed subshell for the final command, Bash executes it in the current, parent shell environment.

A word of warning for those who like to test things live. This magical loophole works beautifully inside saved scripts, but if you try typing it directly into your interactive terminal, Bash will likely ignore you. The terminal environment uses job control, which interferes with this policy. It is strictly a trick for your automated scripts.

The final autopsy report

Bash pipelines are undeniably brilliant mechanisms for shuffling text from one department to another. They are the efficient conveyor belts of the command line. However, we must stop viewing them as simple plumbing. A pipeline is actually a high-security quarantine zone managed by a deeply paranoid human resources department. It operates on a strict policy of total deniability. The exact millisecond the data transfer is complete, the entire department is liquidated with extreme prejudice.

The next time a vital piece of data vanishes without a ransom note after being perfectly processed, resist the urge to question your own sanity. Do not assume you typed the variable name incorrectly. Instead, look closely at your syntax. Look for that single, innocent-looking vertical bar.

The pipe symbol looks like a harmless structural pillar holding your commands together. In reality, it is a locked door behind which your local variables are quietly smothered with a bureaucratic pillow. Your data was not misplaced due to bad code. It was simply assigned to a temporary employee who was instantly fired, erased from the corporate registry, and escorted off the premises before they could hand you the final report. Welcome to Bash administration. The bureaucracy always wins, but at least now you know how to forge the paperwork.

Poking dead servers with a long stick

Let us discuss the biological absurdity of the modern distributed system. You took a perfectly healthy, monolithic software organism and chopped it into a thousand fleshy little pieces, hoping they would communicate flawlessly via telepathy. Congratulations on your trendy new microservice architecture. You have not eliminated failure. You have merely sprayed it across a much wider geographic area, much like a sneeze in a crowded elevator. Now, instead of one predictable, honest crash, you get the distinct thrill of watching a single sluggish database slowly asphyxiate an entire ecommerce empire.

Welcome to the domino effect of modern software anatomy.

The pathology of a fragile network

Networks are pathological liars. They will hand you a glossy brochure promising 99.99 percent absolute uptime, but they will gladly drop your data packets into a black void the moment a slightly distracted contractor named Gary clips a buried fiber optic cable with a backhoe in rural Nevada. The physical reality of the internet is just dirt, glass, and human error.

When Service A politely asks Service B for a user profile, and Service B decides to take a spontaneous, catatonic nap, Service A does not simply walk away. It stands there. It holds open a network connection, consumes a vital thread of server memory, and stares blankly into the middle distance.

If you multiply this behavior by ten thousand concurrent users, you trigger a physiological crisis known as thread pool exhaustion. Your servers are now experiencing the digital equivalent of full organ failure. They are holding their breath, turning blue, waiting for a response that will never, ever arrive. The entire system locks up, your CEO’s pager shrieks at three in the morning, and you are left in the unenviable position of explaining why a minor hiccup in a wildly unpopular newsletter signup widget successfully assassinated the global payment gateway.

Treating your infrastructure like a flaky friend

To survive this architectural nightmare, you must abandon the delusion that your servers are reliable professionals. You must treat them like that one unreliable acquaintance who constantly forgets their wallet at dinner and occasionally faints in public. You need to implement an intervention. You need a circuit breaker.

The humble timeout is your first line of defense. This is the fine art of setting a strict, unyielding timer on your own patience. If a downstream service does not respond in two hundred milliseconds, you violently sever the connection. It is exactly like walking away from a barista who has been staring unblinkingly at a single coffee bean for ten consecutive minutes while a line forms out the cafe door. A timeout ensures your system does not waste precious metabolic energy waiting for a lost cause.

Sometimes, of course, a failure is just a biological blip. A momentary digital hiccup. So, you retry the request. But here lies a fatal trap for the overly optimistic engineer. If five thousand instances of your application instantly retry a failing API at the same millisecond, you have not built a resilient system. You have built a self-inflicted stampede.

You must use exponential backoff, which means waiting longer between each frantic attempt, combined with jitter, which adds a sprinkle of mathematical randomness to the wait time. Instead of your requests acting like a synchronized mob of impatient shoppers trying to smash through the glass doors of a mall on Black Friday, they behave like a group of mildly awkward guests politely knocking on a bathroom door at totally irregular intervals.

The anatomy of an electrical intervention

Circuit breakers have three distinct physiological states, and they operate much like a stressed human nervous system. We begin with the closed state. In electrical terms, closed means the current is flowing beautifully. The system silently monitors the background failures, much like your immune system quietly disposes of mutant cells without bothering your conscious brain. As long as the error rate stays below a defined threshold, the circuit remains closed. Ignorance, in this highly specific context, is pure bliss.

But once the failures cross your designated threshold, say, fifty percent of requests vanish into the ether within ten seconds, the circuit violently opens. The breaker trips. All subsequent calls to the failing service are instantly blocked. No waiting, no polite timeouts, just an immediate and hard refusal.

Think of the open state as a digital restraining order. You are giving the overwhelmed, hyperventilating downstream service a chance to breathe, reboot, or extinguish whichever physical server rack is currently melting into a puddle of expensive plastic. You amputate the limb to save the patient.

Eventually, you need to know if the fire is out. After a mandatory cooldown period, the breaker enters the half-open state. It cautiously lets one or two requests slip through the barricade to test the waters. This is the architectural equivalent of poking a corpse with a very long stick to see if it twitches. If those brave scout requests succeed, the system assumes a resurrection has occurred, the circuit closes, and normal traffic resumes. If they fail, the breaker snaps open again, and the waiting period restarts from scratch.

Handing out cardboard boxes to angry toddlers

When the circuit is aggressively open, you need a backup plan. You cannot just leave your users staring at a blank screen. This concept is called graceful degradation.

If your ultra-personalized, wildly expensive artificial intelligence recommendation engine falls unconscious, you do not throw a catastrophic internal server error at your customer. You return a static, heavily cached list of generic top-selling items. It is the exact equivalent of handing a toddler an empty cardboard box because their expensive remote control car just shattered into pieces against a wall. They will not love the box quite as much, but it distracts them, it provides a fleeting moment of joy, and most importantly, it stops the screaming.

How to avoid going to jail over a toaster

We must read the fine print before you run off to implement this on your production servers. Do not casually throw retries at every single problem you encounter.

Retrying a read request, like fetching a user profile picture, is perfectly safe. Retrying a write request that is not idempotent, like charging a credit card, is exactly how you end up the star defendant in a messy class action lawsuit. If your timeout triggered merely milliseconds after the payment processor actually received the initial request, hitting retry means the customer just bought that premium stainless steel toaster twice. Or perhaps three times, depending on how aggressively your system panicked. Your users will not be amused when a pallet of kitchen appliances arrives at their front door.

Furthermore, you must beware of nested timeouts. If your primary API gateway has a timeout of two seconds, but the underlying microservice deep in the server basement has a timeout of five seconds, the gateway will hang up the phone on the client long before the job is done. Meanwhile, the microservice is still cheerfully crunching data in the dark, entirely unaware that the customer has already left.

It is a spectacular waste of compute power. It is akin to a Michelin star chef meticulously garnishing a five-course meal for a restaurant guest who already climbed out the bathroom window and is currently sprinting down the highway.

Ultimately, building resilient systems is not about preventing failure. Believing you can prevent failure is a delusion reserved for people who do not work with computers. Failure is a mathematical certainty, an inevitable decay akin to biological aging. True engineering is about orchestrating that failure so elegantly, so quietly, that nobody notices the kitchen is currently engulfed in flames. You design for disaster, you code for catastrophe, and then, miraculously, you might just get to sleep through the night without your pager screaming at you about a dead database.

Stop using RSA just because it looks appropriately heavy

A few years ago, a colleague sent me an SSH public key so I could grant them access to one of our servers. I opened the file, looked at it, and immediately frowned.

It looked like this:

ssh-ed25519 AAAAC3NzaC1lZDI1NTE5AAAAIAAAAAwA...

It was tiny. It looked like a typo. It looked like something a cat would produce by walking across a keyboard on its way to the food bowl.

I had spent my entire professional life dealing with RSA keys. RSA keys are the cryptographic equivalent of a 1970s Buick. They are massive. They take up three parking spaces in your terminal window. They practically come with their own zip code:

ssh-rsa AAAAB3NzaC1yc2EAAAADAQABAAABAQ... [insert three paragraphs of gibberish here]

My first reaction was simple, visceral, and completely wrong: This can’t be secure. It’s too small.

I assumed my colleague had made a mistake. Perhaps they had prematurely hit ‘Enter’, or their copy-paste buffer had suffered a catastrophic failure. So, with the gentle, patronizing tone of a seasoned sysadmin, I emailed them back and asked for a “proper” key. You know, an adult key. A key with some girth to it.

After a bit of light reading, and a healthy dose of public humiliation, I realized I was the idiot in this transaction. That short little string wasn’t broken. It was an ED25519 key. And as it turns out, it is superior to my beloved, lumbering RSA keys in almost every conceivable way.

Here is why you need to stop size shaming modern SSH keys, and why ED25519 is the tiny, aggressive honey badger of cryptography.

1. The agony of matchmaking vs. the beauty of chaos

To understand why ED25519 is better, you have to look at how these keys are born.

Creating an RSA key is like playing an exhausting game of mathematical matchmaking. The algorithm requires you to find two massive, entirely random prime numbers, and then multiply them together. The security of RSA relies on the fact that while multiplying two giant primes is easy for a computer, figuring out which two primes were multiplied together (factoring) is incredibly hard.

But there’s a catch. Finding those primes is tedious. The code required to generate and verify them is complex. And if your random number generator is even slightly flawed, or if the code is compromised, which has famously happened before, you end up with a weak, easily crackable key. RSA is picky. It demands very specific, artisanal, farm-to-table numbers.

ED25519, on the other hand, is gloriously unpretentious.

It is based on Elliptic Curve Cryptography (specifically, Twisted Edwards curves, which sounds less like math and more like a Victorian stomach ailment). Because of how elliptic curves work, ED25519 doesn’t need two massive primes. It just needs a random number. Any random number. Give it 32 bytes of pure, unadulterated digital chaos, and it says, “Perfect, I can work with this.” It’s simpler, less prone to implementation errors, and incredibly resilient.

2. It packs a bigger punch in a smaller package

Despite being roughly a sixth of the size of a standard 4096-bit RSA key, an ED25519 key provides an equivalent, if not higher, level of security.

In cryptography, bigger isn’t inherently better; it just means the math you’re relying on is less efficient. RSA is a relic of an era relying on integer factorization. ED25519 relies on the discrete logarithm problem for elliptic curves. I won’t bore you with the math, mostly because I don’t want to explain it, but the practical result is that an attacker would need vastly more computing power to crack an ED25519 key than an RSA key of equivalent security level.

3. It’s fast. Disgustingly fast.

Because RSA keys are so massive, they take a measurable amount of time to generate. You run ssh-keygen -t rsa -b 4096, and you have enough time to take a sip of coffee while the computer sweats through the prime hunting process.

ED25519 keys generate almost instantaneously. More importantly, they are incredibly fast at the two things that actually matter day-to-day. Signing and verifying. When you log into a server, the authentication handshake happens faster, reducing CPU load. It also has the added benefit of being immune to certain side-channel attacks, where hackers monitor how long it takes your CPU to process a password to guess what it is. ED25519 operations run in “constant time,” meaning it gives attackers absolutely nothing to work with.

Embrace the tiny key

It took a bruised ego for me to let go of my RSA comfort blanket. But technology moves on. We no longer use vacuum tubes, we no longer print out MapQuest directions, and we no longer need our SSH keys to look like the terms and conditions of an iTunes update.

If you are still generating RSA keys, do yourself (and your servers) a favor. Type ssh-keygen -t ed25519. Embrace the tiny key. It won’t let you down.